
Key Takeaways
- Begin with the question your research must answer, not a preferred tool.
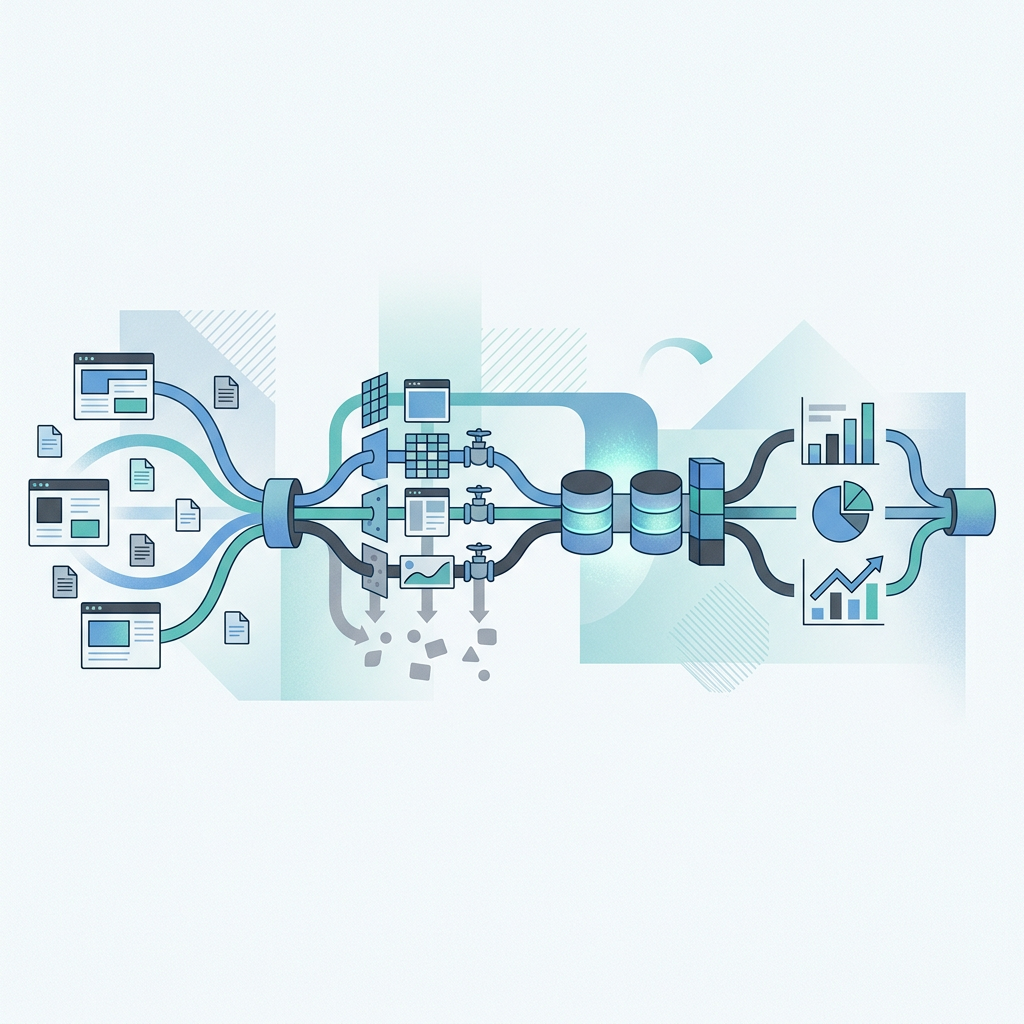
- Separate discovery, retrieval, extraction, cleaning, storage, analysis, and review.
- Measure quality, speed, failure rates, and total cost before scaling.
- Keep source records and human review steps attached to important outputs.
- Choose hosted or self-managed systems based on operational capacity, privacy needs, and control.
AI research depends on information that is current enough for the task, structured enough for analysis, and traceable enough to verify. A quick web lookup may answer a simple question, but a repeatable workflow helps a team collect, compare, and revisit evidence without having to rebuild the process each time.
Tool selection should follow the job at hand. Teams comparing Firecrawl competitors should first decide whether they need to discover new pages, extract content from known URLs, crawl a domain, render browser-based pages, or monitor changes over time. Those are related needs, but they are not the same problem.
Why Web Data Workflows Matter for AI Research
A reliable workflow turns a broad question into a documented process. For example, a market-monitoring project may need to locate company announcements, collect public reports, extract dates and product details, identify changes, and provide an analyst with the original pages underlying each conclusion. Treating those tasks as separate stages makes failures easier to spot and correct.
Start With the Research Question
Write the question in a form that can be tested. “What changed in this market during the past month?” is more useful when paired with source types, date boundaries, expected fields, and a definition of what counts as a meaningful change.
- Known-page extraction: Read a list of URLs you already have.
- Open-web discovery: Find relevant pages from a topic or entity query.
- Site crawling: Follow links across a defined domain.
- Structured collection: Return fields such as title, date, price, or contact name.
- Monitoring: Recheck selected sources on a schedule.
A page extractor can be excellent for known URLs while offering little help when the task begins with an open-ended question. Define the starting point before comparing features.
The Main Parts of a Strong Web Data Pipeline
- Discovery: Find pages, documents, datasets, and relevant source types.
- Retrieval: Fetch selected pages and files with timeouts and status logging.
- Rendering: Load content that appears only after JavaScript or browser interaction.
- Extraction: Remove navigation, ads, repeated page elements, and unrelated text.
- Cleaning: Normalize dates, names, units, labels, and missing values.
- Storage: Save the URL, access time, extracted fields, and workflow version.
- Analysis and review: Use models, scripts, or people to interpret findings and verify important claims.
Compare Tools by Job, Not Feature Count
Long feature lists can hide critical gaps. Compare candidates against the work each stage requires:
- Finding relevant pages: Can the system search and rank pages for the research question?
- Reading known URLs: Does it return clean text, useful metadata, and the original address?
- Crawling a site: Can it follow useful links while avoiding duplicate records and irrelevant paths?
- Handling dynamic pages: Can it render content loaded after the initial page response?
- Producing business fields: Can output follow a defined schema and flag missing values?
- Tracking change: Can repeated runs identify what changed and when?
Set Quality Checks Before Scaling
Run a small, varied test set before collecting thousands of pages. Include simple articles, pages with repeated layouts, dynamic pages, files, and pages likely to fail. Check search precision, whether useful sources were missed, field-level accuracy, page success rate, response time, cost per completed record, and the share of records needing human correction.
Keep failed pages in the results instead of silently dropping them. A visible failure record is more useful than a dataset that appears complete but excludes inaccessible or misread sources.
Plan for Pages That Break
Websites evolve over time. A reliable workflow must address JavaScript-heavy pages, temporary errors, rate limits, broken links, duplicate content, layout modifications, and unexpected file formats. Implement retry limits, backoff strategies, timeouts, duplicate detection, and a manual review queue to effectively manage these challenges.
Choose Hosted or Self-Managed Systems
Hosted Systems
Hosted services can reduce setup work and help small teams test quickly. The trade-off may include recurring usage charges, reduced control over processing, and the need to assess how the provider’s handling aligns with internal data policies.
Self-Managed Systems
Self-managed systems offer more control over storage, processing, customization, and vendor dependence. They also require engineering time for infrastructure, browser updates, monitoring, and maintenance. Choose managed services when speed is the priority, and self-managed systems when control or data policy carries greater weight.
Keep Evidence Attached to Output
Every useful record should retain its page address, access timestamp, extracted passage or fields, run identifier, and status. Mark sources that were blocked, incomplete, or changed. This makes it possible to audit an answer rather than asking a model or analyst to reconstruct its provenance later.
For higher-impact uses, connect review rules to the organization’s risk process. The AI Risk Management Framework outlines a voluntary approach to managing AI-related risks, helping teams determine which outputs require stronger documentation and human approval.
Control Cost, Speed, and Human Review
Filter during discovery before retrieving full pages, cache stable content, collect only the necessary fields, and set limits on retries, page counts, and model calls. Track cost per useful answer, not merely cost per request. A low-cost extraction that repeatedly needs repair may be more expensive than a cleaner result.
Use people where judgment matters most: sensitive claims, unusual changes, high-risk decisions, and records entering customer-facing systems. Review heavily during pilot runs, then reduce manual checks only after performance remains stable across varied sources.
A Practical Selection Process
- Define the research goal, source types, fields, and acceptable error level.
- Select a small group of tools that match the required stages.
- Run the same test set through each option.
- Compare accuracy, speed, failure patterns, privacy terms, support, and total cost.
- Launch a limited production pilot and retest when sources or requirements change.
Conclusion
A reliable web data workflow starts with a precise question and ends with evidence that another person can inspect. The strongest system is not the one with the longest feature list. It is the one that finds useful sources, handles failure honestly, controls cost, and supports decisions with traceable records.
Discover more from The Cameron Journal
Subscribe to get the latest posts sent to your email.




